← Back to live feed · 1 stories across 1 day
Thursday, Sep 17, 2026
1 story1 NEWDeepSeek V4.1 Flash Cuts Prefill Compute 50% in Shift From Standard Transformer AI Sep 16, 11:26 PM EDT 4/3 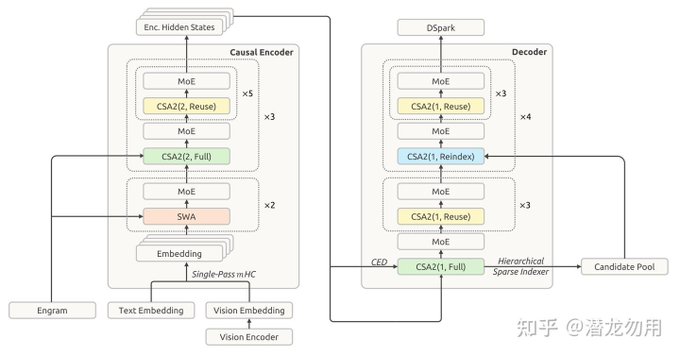
DeepSeek-V4.1-Flash employs a Causal Encoder-Decoder design that activates 8B parameters per prefill token compared to 16B per decode token. The model 40 layer backbone splits into a 20 layer causal encoder for prompt processing and a 20 layer decoder for token generation, which reduces compute overhead for long inputs by roughly 50%. A memory sharing system called CSA2 reduces the KV cache, while mHC kernel optimizations lower communication overhead between SM and HBM.
The architecture incorporates FP4 global KV to lower the cache to 890 bytes per token and trains the model to tolerate approximations using only the final 128 encoder outputs. Increasing reasoning effort from 25 to 100 raised the average Pass@1 across eight benchmarks from 67.1% to 76.3% and increased output length 2.5 times. These design choices align model structure and retrieval limits with the constraints of deployed long running Agents.