← Back to live feed · 1 stories across 1 day
Friday, Sep 18, 2026
1 story1 Epoch AI Labels 9 of 15 AI Benchmarks Flawed in Debut Audit AI Sep 17, 5:53 PM EDT 16/12 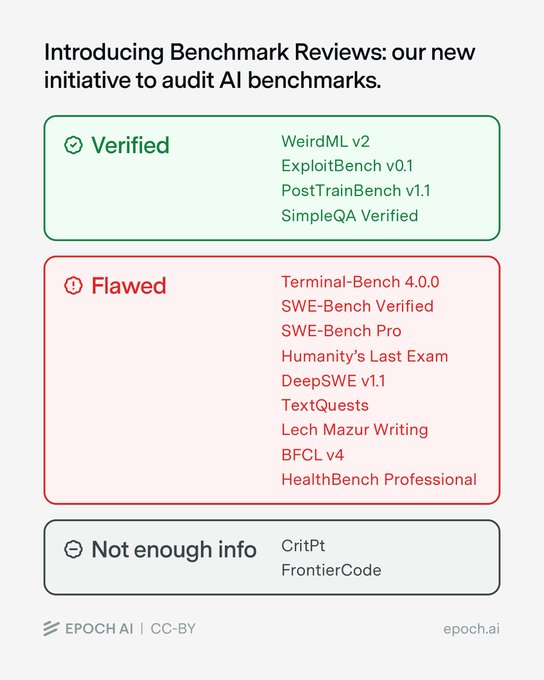
Epoch AI's Benchmark Reviews initiative evaluates the quality of tools used to measure artificial intelligence capabilities. The first assessment of 15 benchmarks designated 9 as flawed, while 4 were verified and 2 lacked enough information for a review. Findings showed that 45.5% of tasks in Terminal Bench 4.0 were broken, and 46% of randomly sampled questions in the HLE benchmark were also found to be faulty.
Audit results for DeepSWE 1.1 identified a bug capable of breaking grading for every task and 23 false negatives out of 131 tasks, which creates an artificial performance ceiling of 79.6%. The verifier in that benchmark discards agent changes to some test files without notifying the model, leading to irrelevant failures. Epoch AI publishes full assessments for all verified benchmarks to create a consistent quality standard and incentivize higher industry benchmarks.