← Back to live feed · 1 stories across 1 day
Tuesday, Sep 22, 2026
1 story1 Grok 4.7 Uses 125% More Output Tokens on Intelligence Benchmark AI Sep 21, 11:39 PM EDT 99/45 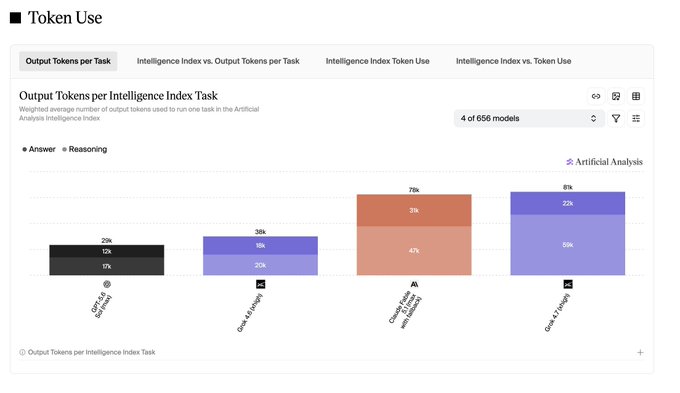
SpaceXAI's Grok 4.7 scored 46 on the Artificial Analysis Intelligence Index, two points above Grok 4.6, while using about 81,000 output tokens per task versus 36,000 — an increase of 125%. The evaluation compared Grok 4.7 at xhigh reasoning effort with Grok 4.6 at high. Base prices remain $2 per million input tokens and $6 per million output tokens.
Released Sept. 21 in Cursor, Grok Build and the Grok API, the model improved more on coding and professional work. Paired with Grok Build, it scored 56 on the Artificial Analysis Coding Agent Index, up from 47 for Grok 4.6, with both tested at xhigh. It also gained 111 Elo points on AA-Briefcase, which tests professional tasks. Artificial Analysis put the cost of producing example due diligence decks at about $8, versus $4.40 for Grok 4.6, while finding stronger analytical quality.
Other evaluations were mixed. Cognition found Grok 4.7 slightly behind its predecessor on FrontierCode 1.1, saying it tended to expand the scope of some tasks too far. Vals initially ranked it 24th on its index, down from Grok 4.6's 14th place, but raised it to 10th after SpaceXAI updated its software development kit. Theo challenged the model's efficiency claims: "I have yet to find a single bench where Grok 4.7 is more token-efficient than Grok 4.6."