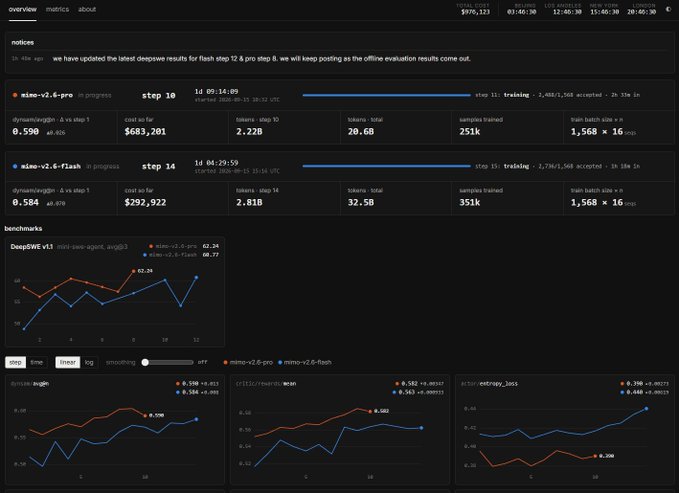
The current reinforcement learning training for MiMo-V2.6 integrates multi-task agentic RL across multiple environments in a single run. This process utilizes approximately 2 billion tokens per step and combines 1,568 prompts with 16 rollouts in a fully asynchronous architecture. Grader compute incorporates agentic in-group credit assignment and uses rubric-based rewards.
The project follows a 6 month study on how reinforcement learning scales as a means of model self-improvement. Technical specifications of the V2.6 RL run will be open sourced piece by piece over the coming weeks, while a live stream of the process is currently available.
You're reading an older version of the story.