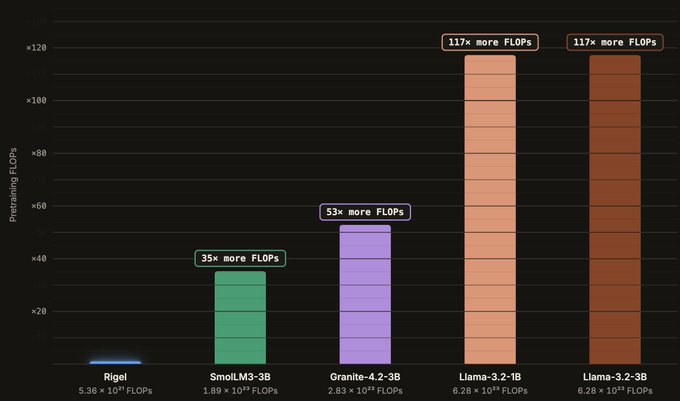
Mayank Mishr developed a 2.3B parameter mixture-of-experts model called Rigel that performs within a few points of Meta's Llama-3.2-3B. The Hybrid Mamba-2 architecture utilizes 360M active parameters and required less than 1% of the pretraining floating point operations (FLOPs) used for the larger model.
The training process utilized a single codebase without a dedicated cluster, alternating between Nvidia H100, A100, and V100 GPUs along with Google TPU v5p and v6e accelerators. This run spanned three generations of Nvidia hardware and two generations of TPUs to reach its performance benchmarks.
You're reading an older version of the story.