← Back to live feed · 1 stories across 1 day
Wednesday, Sep 23, 2026
1 story1 Rigel 2.3B Model Rivals Llama-3.2-3B With <1% Pretraining Compute AI Sep 22, 11:37 PM EDT 6/6 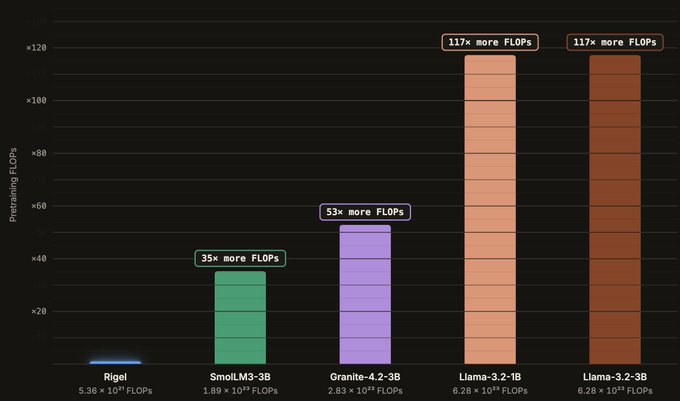
A new machine learning architecture called Rigel has produced performance results comparable to Meta's Llama-3.2-3B using a reduced compute footprint. Developed by Mayank Mishkin and a research team, the 2.3B parameter Mixture-of-Experts (MoE) model employs a Hybrid Mamba-2 design with 360M active parameters to score within a few points of the Meta model while using less than 1% of its pretraining floating-point operations (FLOPs).
The model was developed without a dedicated compute cluster, instead utilizing a "guerrilla style" strategy that shifted a single codebase across fragmented resources. This training run moved between Nvidia H100, A100, and V100 GPUs as well as TPU v5p and v6e processors, demonstrating a method for conducting large-scale academic pretraining without unified supercomputing hardware.