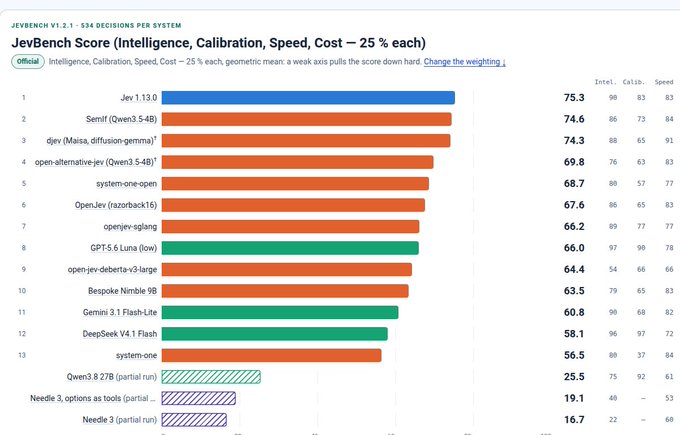
Typesafe AI's Jev decision model processed bounded software decisions more than 5 times faster than competing large language models. Tests by OpenRouter using Ori Eval showed Jev's slowest requests beat the median speed of other models, while its operational cost ranked as the second lowest behind Qwen3.8 Flash.
The Sept. 15 release provides typed answers with probabilities instead of open-ended prose to optimize for deployment speed. In the JevBench composite score, which blends intelligence, calibration, and cost, Jev outperformed GPT-5.6 Luna despite the latter having higher accuracy in hard cases. LangChain analyzed the model to see if System One architectures provide a more repeatable approach to agent evaluation.