← Back to live feed · 1 stories across 1 day
Sunday, Sep 20, 2026
1 story1 TypeSafe Jev Leads First Decision Model Benchmark JevBench With 75.3 Score AI Sep 19, 6:19 PM EDT 11/7 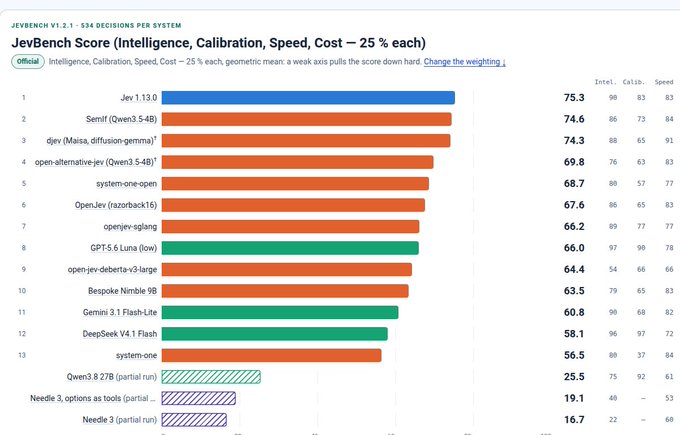
The JevBench metric evaluates AI models that produce bounded software decisions rather than open-ended prose by combining intelligence, calibration, speed, and cost. TypeSafe's Jev model topped the index with 75.3 points, followed by SemIf #2 at 74.6. The benchmark uses a geometric mean to prioritize deployment viability, allowing Jev to outrank models like GPT-5.6 Luna that possess higher raw accuracy but slower response times or higher operating costs.
Developers are applying the decision model to agent verification and online evaluations to reduce reliance on expensive reasoning frameworks. Jev cost $0.064 for 600 judgments in a user test, roughly 90 times less than the $5 cost for Anthropic's Sonnet. Performance tradeoffs persist, however, with Jev showing a 32% false admission rate for negative samples compared to Sonnet's 13.5%.