← Back to live feed · 1 stories across 1 day
Wednesday, Sep 23, 2026
1 story1 Claude Opus 5.5 Tops Artificial Analysis Coding Agent Index at 21% Higher Task Cost↩︎ AI Sep 23, 9:24 PM EDT 109/75 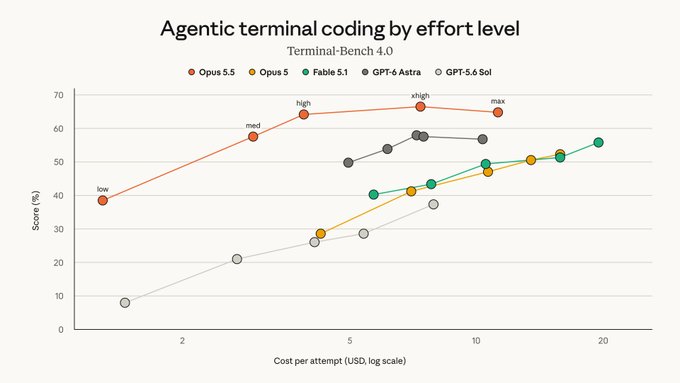
Anthropic’s Claude Opus 5.5 scored 66 on the Artificial Analysis Coding Agent Index when run in Claude Code at maximum effort, beating Opus 5’s 60 and Claude Fable 5.1’s 62. The leading result came at the highest cost per task in the comparison: $13.04, up 21% from $10.79 for Opus 5, despite lower token prices.
Opus 5.5 improved across all three equally weighted evaluations. Terminal-Bench 4.0 rose to 63.1% from 54.5% for Opus 5, the largest gain at 8.6 percentage points. DeepSWE v1.1 increased to 68.4% from 62.5%, while SWE-Atlas-QnA reached 66.4%, up from 62.1%. No cheaper model in the comparison matched Opus 5.5’s overall score.
Higher token use outweighed Anthropic’s price cuts in the coding tests. Opus 5.5 used about 15.6 million tokens per task versus 11.4 million for Opus 5, with output rising to about 333,000 tokens from 137,000. Input and output prices fell 20% to $4 and $20 per million tokens, respectively, while cache reads dropped 60% to $0.20 per million. These maximum effort results cover a different setting from Anthropic’s launch tests, which showed costs 40% below Opus 5 on typical workloads at default settings.