← Back to live feed · 1 stories across 1 day
Thursday, Sep 17, 2026
1 story1 Zai Agent Boosts GLM-5.3-Flash Throughput 3.2 Times in 2 Week Self Optimization AI Sep 17, 3:05 AM EDT 16/15 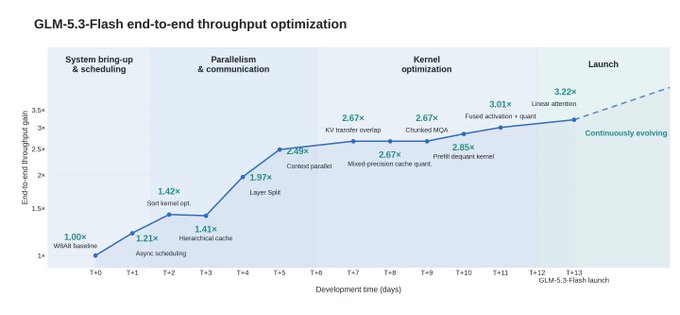
An automated infrastructure tool powered by GLM-5.3 optimized the inference stack for its Flash counterpart on domestic accelerators. The agent transitioned the system from an initial run to production readiness in under 14 days, achieving a 3.2 fold increase in end-to-end throughput. This environment now handles multimodal requests and maintains a 1 million token context window despite an immature software stack and missing kernels.
Zai engineers provided the agent with "dense feedback" including correctness tests and microbenchmarks to isolate faults rather than relying on aggregate metrics. This allowed the AI to cut KV transfer overhead from over 30% to under 1% and accelerate a decode kernel 1.71 times. The project demonstrates a loop where an AI model optimizes the hardware and software systems required to run its successors.