← Back to live feed · 1 stories across 1 day
Friday, Sep 18, 2026
1 story1 Epoch AI Labels 9 of 15 AI Benchmarks Flawed in New Audit AI Sep 17, 8:53 PM EDT 17/13 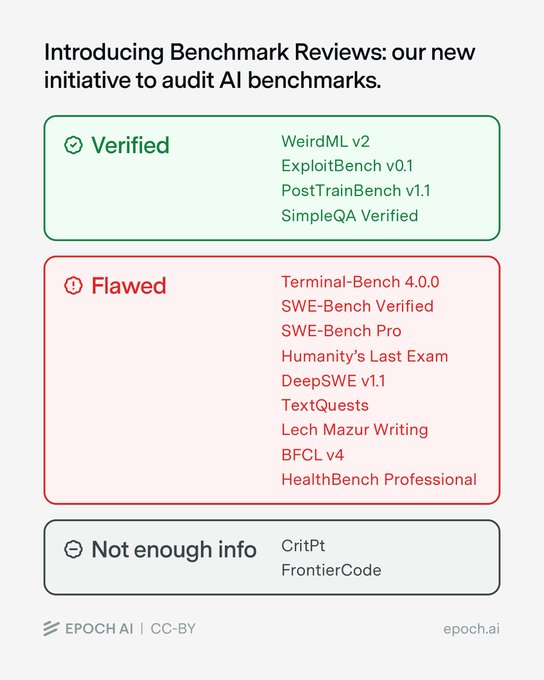
Epoch AI Research released its first set of quality reviews for artificial intelligence benchmarks on Sept. 17. The inaugural phase of the Benchmark Reviews project analyzed 15 evaluation sets, labeling nine as flawed, four as verified, and two as insufficient for review. The organization uses a specific rubric to assign these verdicts, focusing on whether errors in the benchmarks fundamentally alter the results of AI capability tests.
Findings from the audit revealed that 45.5% of tasks in Terminal Bench 4.0 were broken, and 46% of sampled questions in the HLE benchmark were faulty. For DeepSWE v1.1, the audit identified a bug that disrupts grading for all tasks by discarding agent changes to test files without informing the model. To prevent conflicts of interest, the group excludes benchmarks it created from the review process.