A high speed inference tier has been added to the Flash model family through the release of a new API from Zhipu AI. The GLM-5.3-FlashX version reaches 200 tokens per second, a 5 times increase over the previous iteration. Pricing for this tier is ¥2 per million input tokens and ¥7 per million output tokens, which is 2.5 times higher than the original ¥0.8 and ¥2.8 rates.
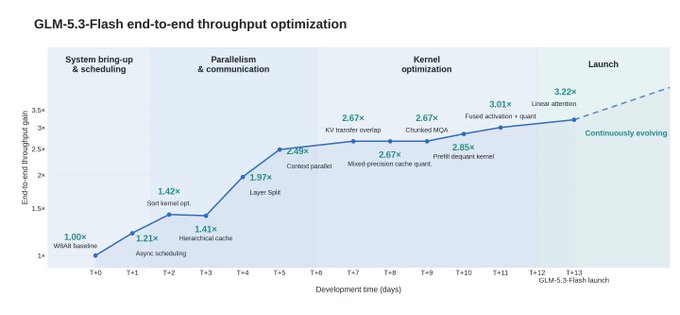
The underlying infrastructure utilizes roughly 100,000 Chinese AI chips. Zhipu disclosed that a GLM-5.3-powered agent optimized the system serving the Flash model in less than two weeks, resulting in 3.2 times the end-to-end throughput compared to the initial baseline before the launch of the FlashX variant.